Deadline Propagation: Why Your p99 Is Just the Sum of Your Timeouts
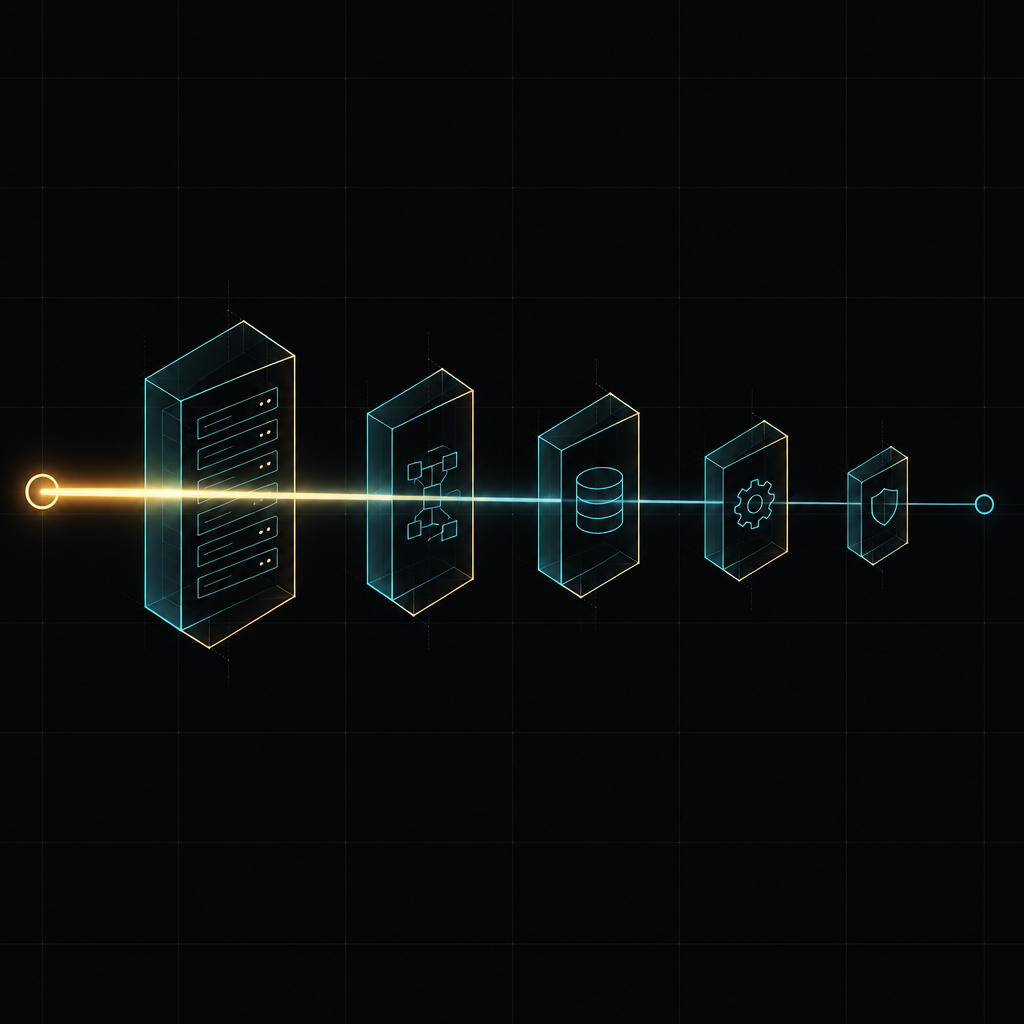
A user taps checkout. The request crosses an edge proxy, an API gateway, an order service, a pricing service, an inventory service and a payment provider. Six hops, five of them internal. Every one of those services has a timeout configured by a different team, in a different quarter, for a different reason.
The p50 is 180ms. The p99 is 4.2 seconds. Nobody chose 4.2 seconds. It is simply the sum of the timeouts.
Every hop picks a number that describes only itself
The usual pattern: a service owner measures their own latency, sees p99 at 800ms, sets the client timeout to 1.5 seconds for "headroom," and moves on. That is a defensible decision made in isolation. Applied six times in a chain, it produces a caller that waits 9 seconds for a request that could only ever succeed in 200ms.
Two compounding effects make it worse than simple addition.
Serial addition. A request that hits the slow tail at every hop accumulates. The probability is low, but you have millions of requests, so the low-probability corner is a permanent feature of your p99 and a daily feature of your p99.9.
Retry multiplication. If each hop retries twice on timeout, the leaf service can see up to 2^5 requests for one user action. The retry storm arrives exactly when the system is already slow, which is the only time it matters.
The deeper problem is not the numbers. It is that the number is a local fact applied to a global question. A timeout is a statement about how long the caller is willing to wait, and only the original caller knows that.
A deadline is data, not configuration
The fix is to pass the caller's remaining patience down the stack as a value that every hop reads and decrements. gRPC has carried this as grpc-timeout for years; HTTP has no equivalent primitive, so you build one.
X-Deadline-Ms: 900
Two rules make it work:
- Absolute, not relative. Send the remaining budget in milliseconds, computed at send time. Never send an absolute wall-clock timestamp; clock skew between hosts turns a budget into a coin flip.
- Each hop subtracts before it forwards. Reserve a slice for your own overhead, pass the remainder down. The leaf gets what is actually left.
The middleware is small:
func withDeadline(next http.Handler) http.Handler {
    return http.HandlerFunc(func(w http.ResponseWriter, r *http.Request) {
        var budget time.Duration
        if h := r.Header.Get("X-Deadline-Ms"); h != "" {
            ms, err := strconv.Atoi(h)
            if err != nil || ms <= 0 {
                http.Error(w, "bad deadline", http.StatusBadRequest)
                return
            }
            budget = time.Duration(ms) * time.Millisecond
        } else {
            budget = defaultBudget // 2000ms at the edge
        }

        // keep 15% (max 40ms) for our own serialization and response write
        reserve := budget / 7
        if reserve > 40*time.Millisecond {
            reserve = 40 * time.Millisecond
        }
        child := budget - reserve
        if child <= 0 {
            http.Error(w, "deadline exceeded", http.StatusGatewayTimeout)
            return
        }

        ctx, cancel := context.WithTimeout(r.Context(), child)
        defer cancel()

        r = r.WithContext(ctx)
        r.Header.Set("X-Deadline-Ms", strconv.Itoa(int(child.Milliseconds())))
        next.ServeHTTP(w, r)
    })
}
The important line is the child <= 0 check. A hop that receives an expired budget should fail immediately and loudly rather than start work it will abandon. Failing fast at the fourth hop is worth more than succeeding slowly at the sixth, because the caller has already given up.
Budget allocation is a fan-out problem, not a chain problem
Linear chains are the easy case. Real services fan out: one order request calls pricing, inventory and fraud in parallel, then waits for all three. If each child gets the full remaining budget, you have not saved anything, you have just moved the deadline around.
Allocate the child budget from the parent's remaining time, and make the parallel calls share it:
child := childBudget(ctx) // parent remaining minus reserve
g, gctx := errgroup.WithContext(ctx)
g.SetLimit(3)
for _, svc := range []string{"pricing", "inventory", "fraud"} {
    svc := svc
    g.Go(func() error { return call(gctx, svc, child) })
}
err := g.Wait()
Two properties fall out of this and both matter:
- One slow dependency cannot exceed the parent's patience. The
gctxcancellation propagates to siblings when the first hard failure occurs, so you stop paying for work whose result you cannot use. - Partial results become possible. If fraud is optional and pricing is not, give fraud a shorter sub-budget and degrade gracefully when it expires, rather than failing the whole request. This is the single highest-leverage use of deadline propagation, and it is a product decision as much as an engineering one.
Retries need a budget, not a count
Per-call retry counts multiply across hops. Retry budgets do not: track the fraction of recent requests that were retries, and stop retrying when that fraction crosses a threshold.
A workable default is a token bucket where retries draw tokens and successes replenish them, with a ceiling of about 10 percent of traffic. Under normal load, retries are free. During an incident, retries are capped and the system sheds load instead of amplifying it. Pair this with the deadline: a retry is only worth attempting if the remaining budget exceeds the cost of a fresh attempt by a healthy margin, typically two to three times the observed p50 for that call.
if remaining < 3 * p50 && retryBudget.Exhausted() {
    return lastErr // do not retry, fail the request fast
}
The counterintuitive part: aggressive retries make p99 worse even when they make p50 better. If your retry policy is not deadline-aware, it is a latency amplifier wearing a reliability costume.
The time you cannot see
The hardest part of a timeout budget is that queueing time is invisible to the caller. A request can spend 700 of its 900 milliseconds waiting in a server's accept queue, a connection pool, or a thread pool, and the application code that receives it sees a fresh context with a nearly expired budget and no explanation.
Three things help:
- Measure admission latency separately from handler latency. Time in the pool is the number that tells you to add capacity; handler latency tells you to change code. Conflating them is how teams end up optimizing the wrong thing.
- Reject on arrival when the budget is already spent. A 503 in 1ms is a gift to the caller. Accepting the work and timing out in 800ms is a waste of the one resource you are short of.
- Keep the reserve generous. The 15 percent reserve in the middleware above is not overhead, it is the cost of telling the caller something useful instead of dropping the connection.
What to measure
Four signals tell you whether the budget is real:
- Deadline rejection rate per hop. Where requests die tells you which dependency is over-budgeted or under-provisioned. A healthy service rejects at its own edge, not deep inside.
- Remaining budget at the leaf. If your leaf services routinely see under 50ms of a 2-second budget, your internal timeouts are decorative.
- Retry fraction. Over 10 percent means timeouts are too tight somewhere upstream; near zero during an incident means they are too loose.
- p99 of total chain latency versus p99 of the slowest hop. These should be close. When the chain is several times the slowest hop, you have serial retries or a hidden queue.
The trade you are making
Deadline propagation costs a header, a middleware, and the discipline to stop thinking of timeouts as per-service settings. In exchange, failure becomes predictable: a request either succeeds within the window the caller specified, or fails fast enough that the caller can do something else.
The second-order benefit is the one teams underestimate. Once every hop knows how much time is left, "slow" stops being a mystery and becomes a routing decision. Degrade the optional dependency, serve the cached price, return a partial result. That is not a fallback pattern you bolt on later. It is what a shared clock makes possible.
Zero-X platform primitives include deadline propagation across internal service calls, per-call retry budgets, and admission-time rejection for requests whose budget is already spent.
We use cookies to improve your experience on this site. By continuing, you agree to our Privacy Notice.